 NEXT4I
enAIEngineerRAGAIDeveloperAIBuildInPublic
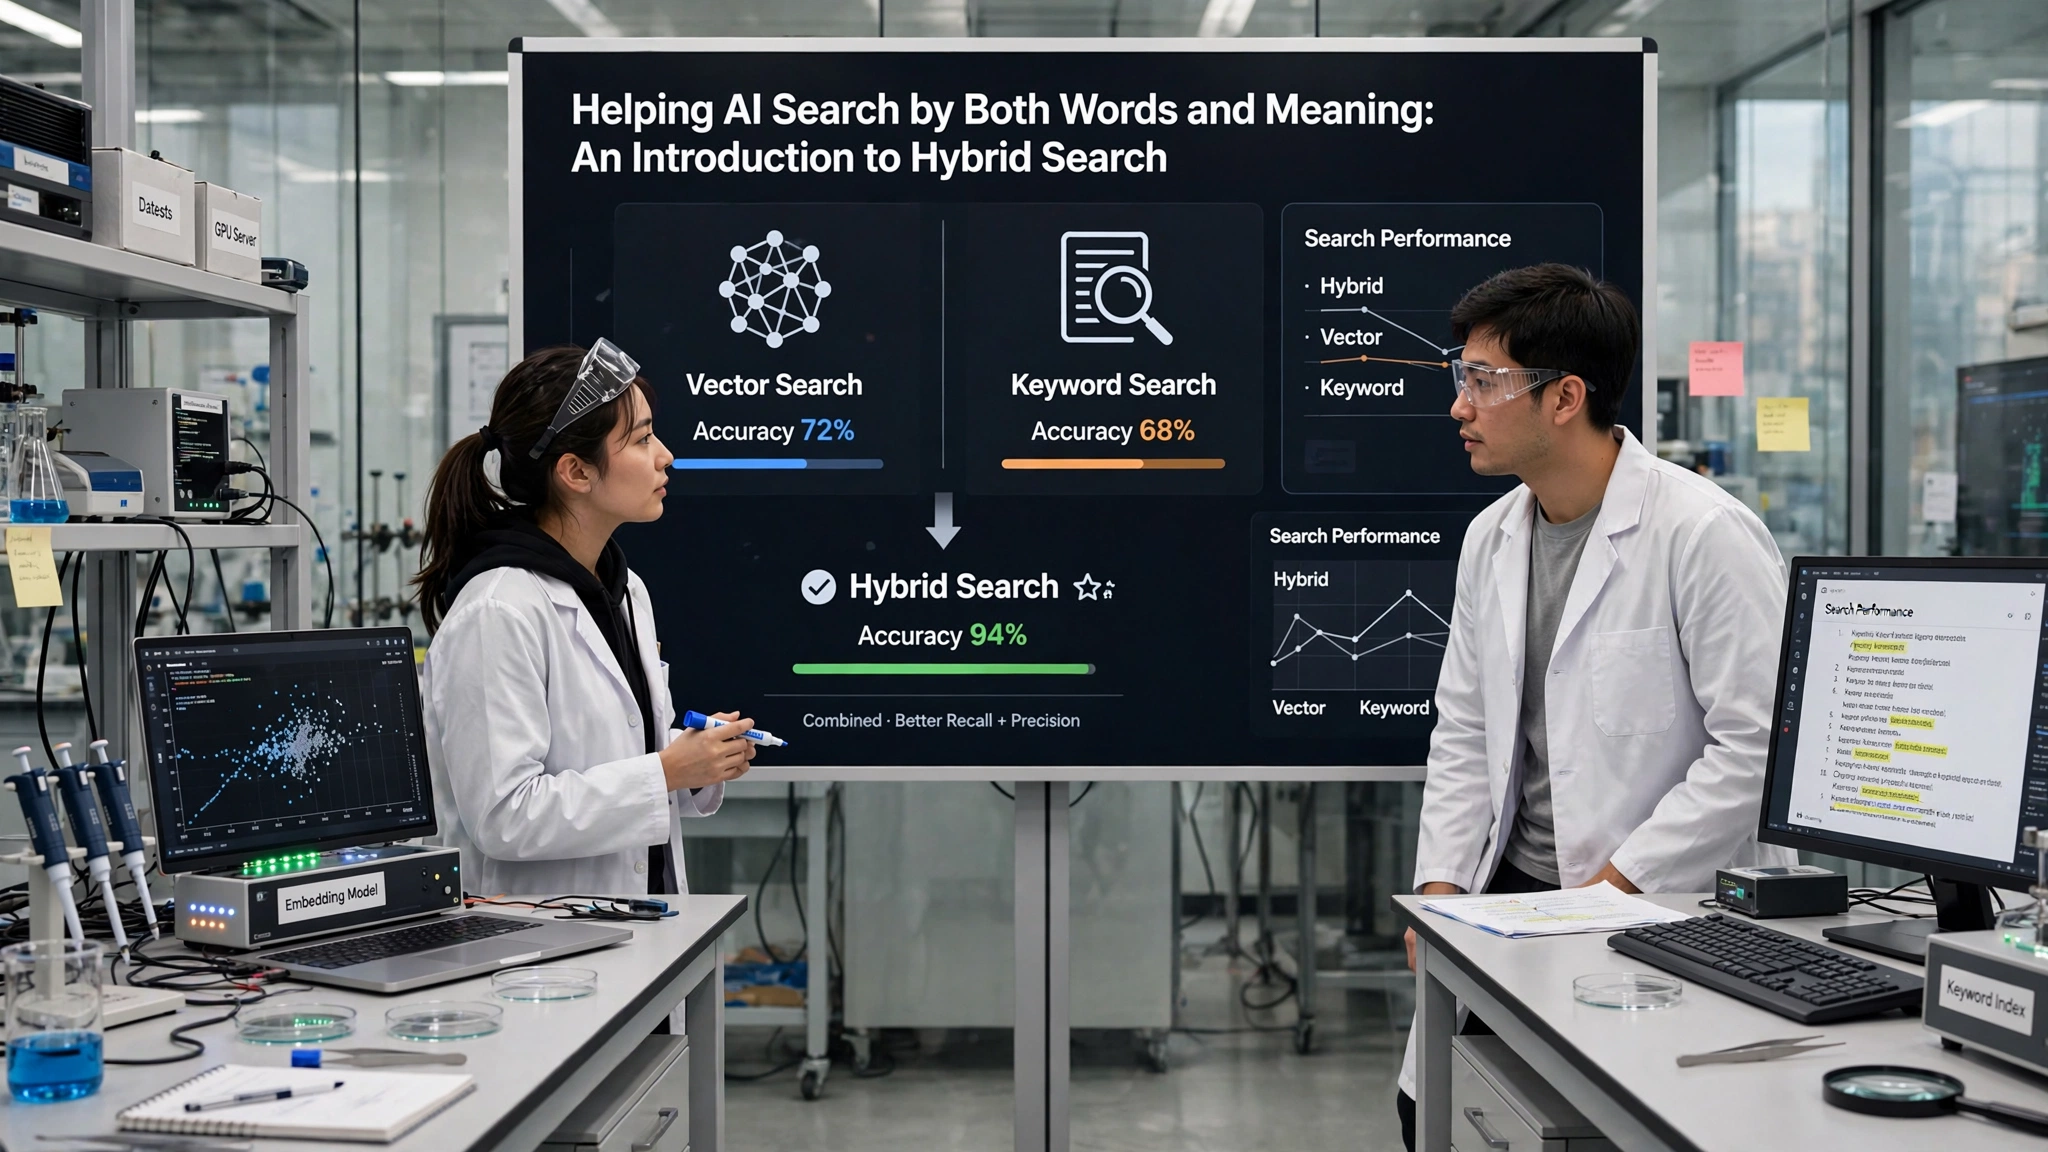
Hybrid Search Explained: Why Vector Search Still Needs Keywords
Hybrid search combines semantic and keyword retrieval so systems can find both intended meaning and the specific terms that matter.
Shared knowledge from NEXT4I and the web community.
Hybrid search combines semantic and keyword retrieval so systems can find both intended meaning and the specific terms that matter.
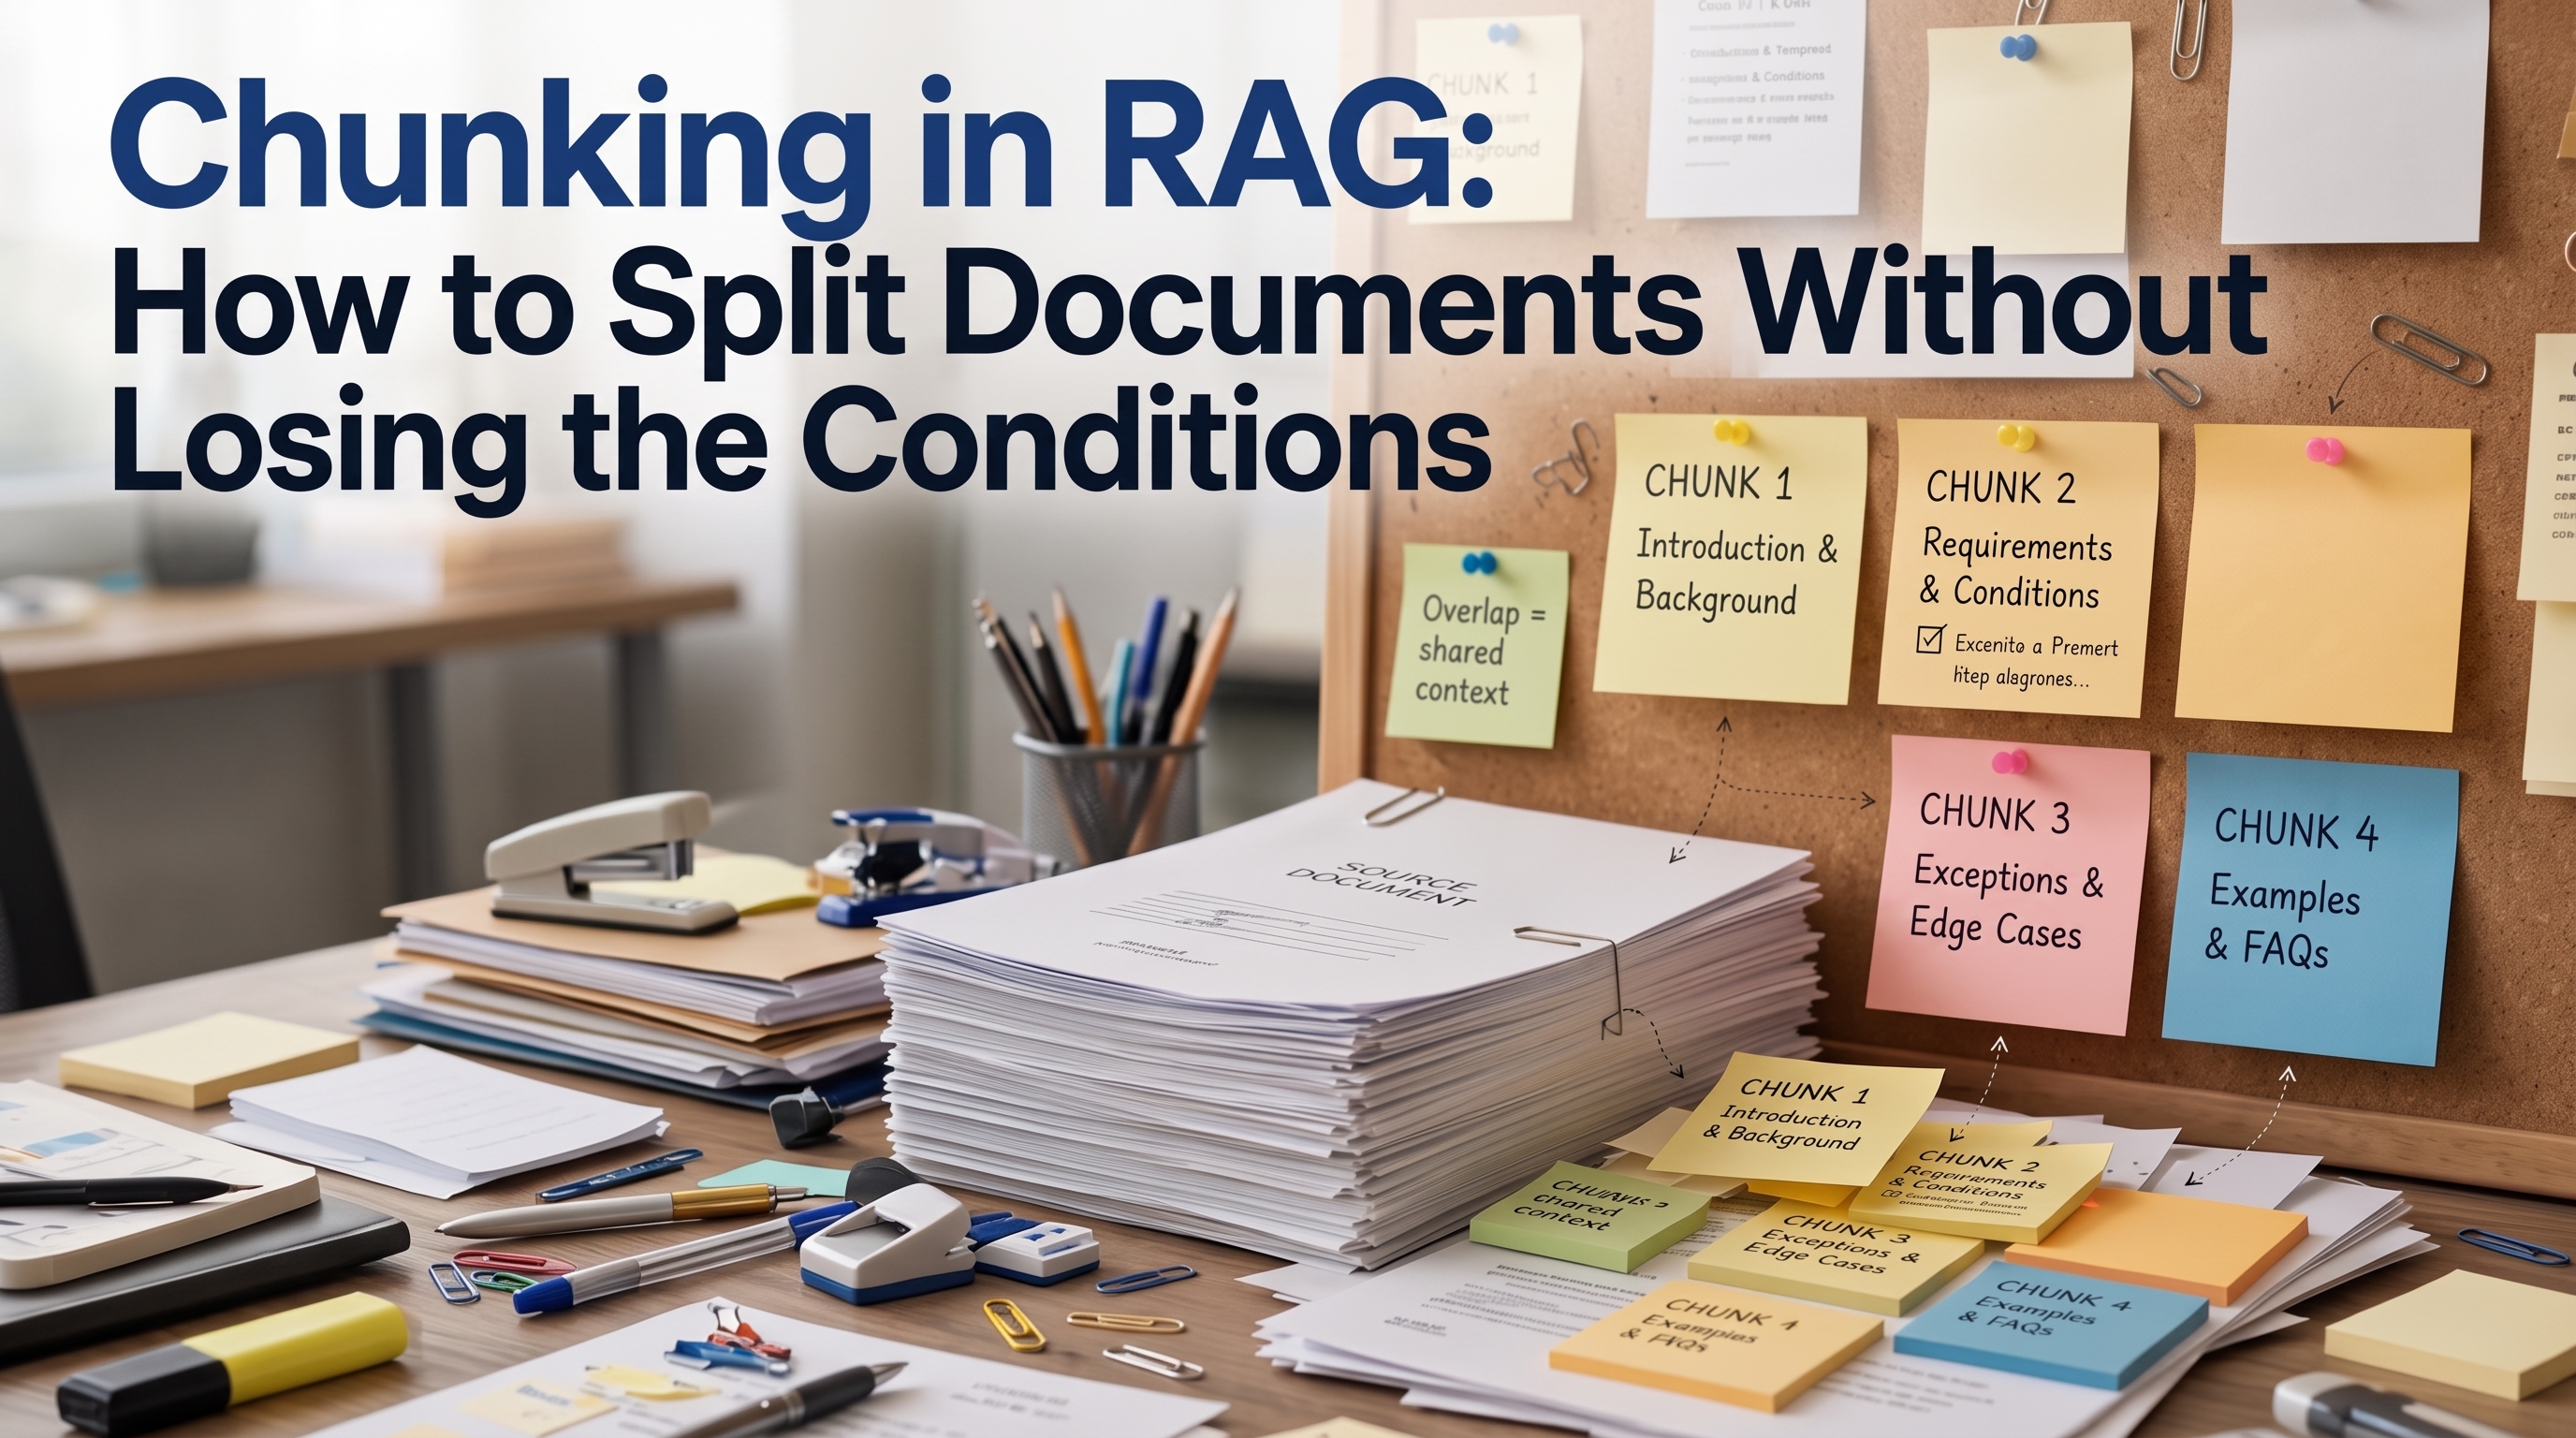
That failure can start before generation, at the document boundary. **Chunking in RAG is not about making text as small as possible.
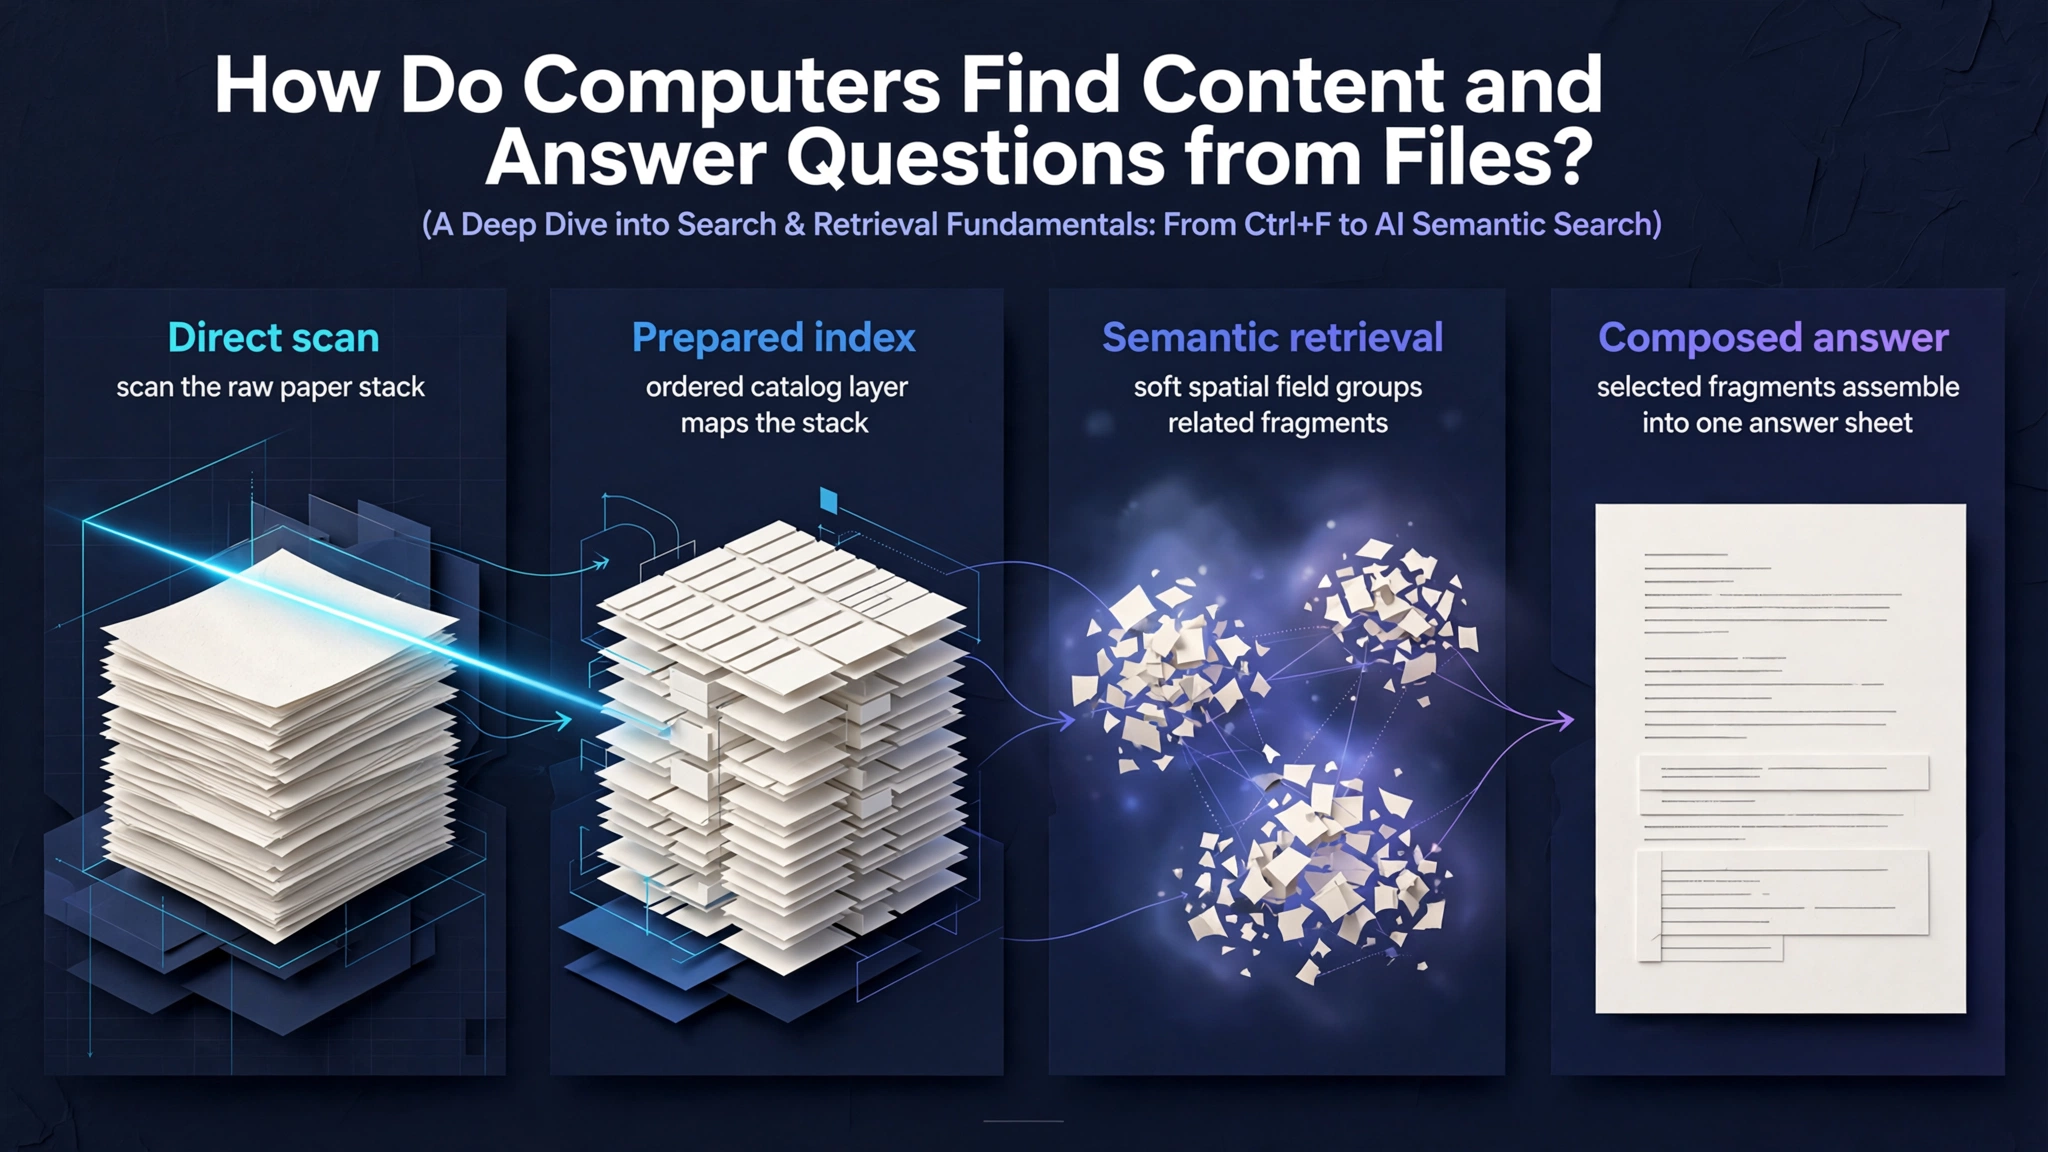
Finding Content and Answering Questions directly from Files: Most people who work with documents have faced some version of this problem
Connecting an LLM to an application is the easy part of a RAG demo. The difficult part starts when the source is a real document instead of a clean string in an array.
A prompt can tell an agent what to do once. A skill file can document how a team handles that class of work repeatedly.
What Is a Token in LLMs? A Developer's Guide to Cost Optimization and Architecture. Understanding how LLM tokens work is the difference between an AI feature that costs $50/month
Why treating an LLM as a probability engine, not a brain, changes how you architect around it. The reasoning behind NEXT4I's AI layer.
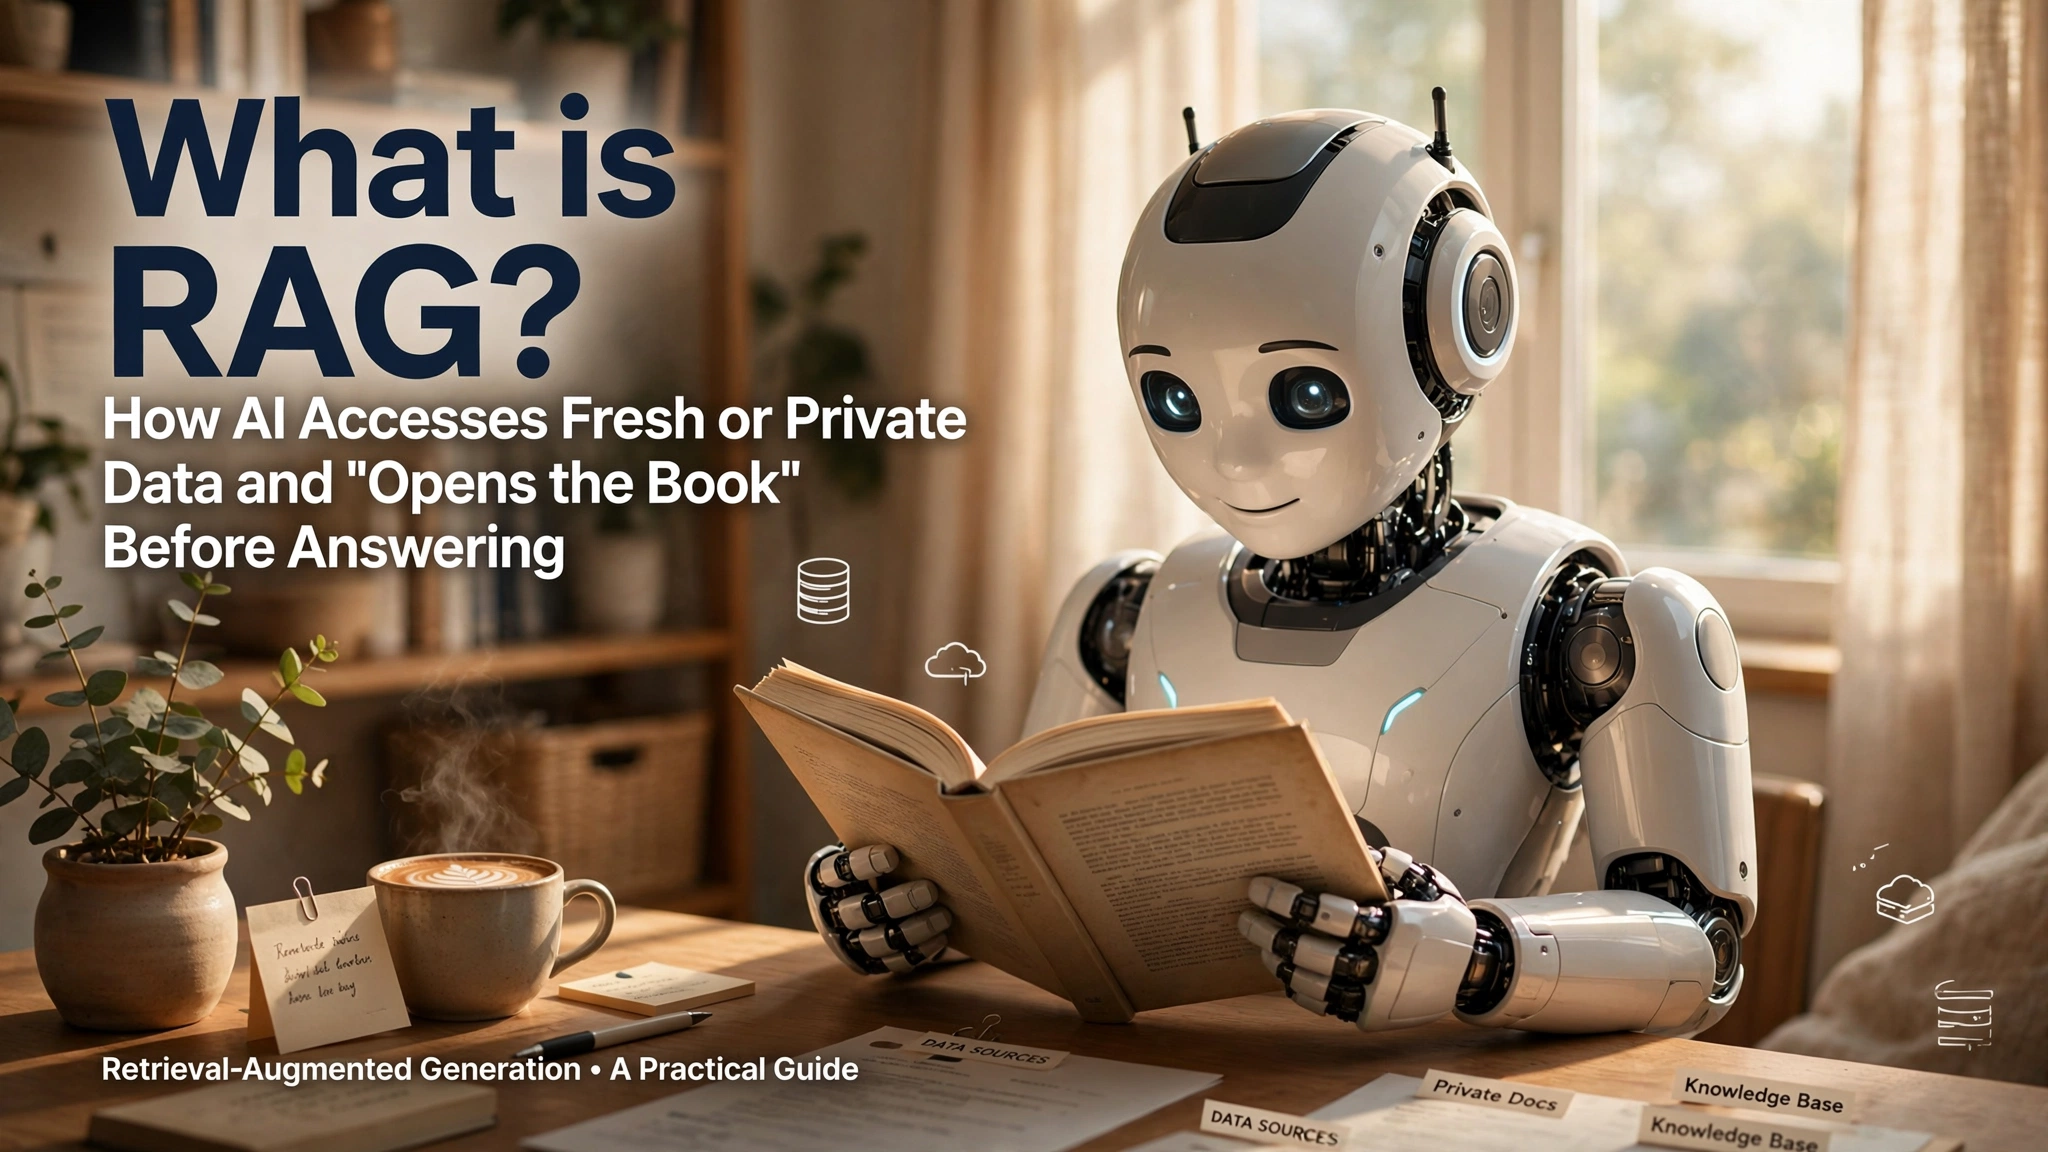
I was building a RAG (Retrieval-Augmented Generation) pipeline for NEXT4I the kind of system that reads your documents first, then answers questions from them. Standard stuff: document ingestion → chunking → embedding → vector search → LLM answer generation.
Connecting Obsidian, Git, and AI Agents with nothing but plain Markdown. The Seamless Integration by Design philosophy from NEXT4I.
ลงชื่อเพื่อรับแจ้งเตือน และร่วมเป็นผู้ใช้งานกลุ่มแรกพร้อมรับสิทธิพิเศษ
Drop your email to get notified. Early access members get exclusive perks!
We hate spam as much as you do. Only big updates, no junk.
No subscriptions. No annual fees. No lock-ins.